
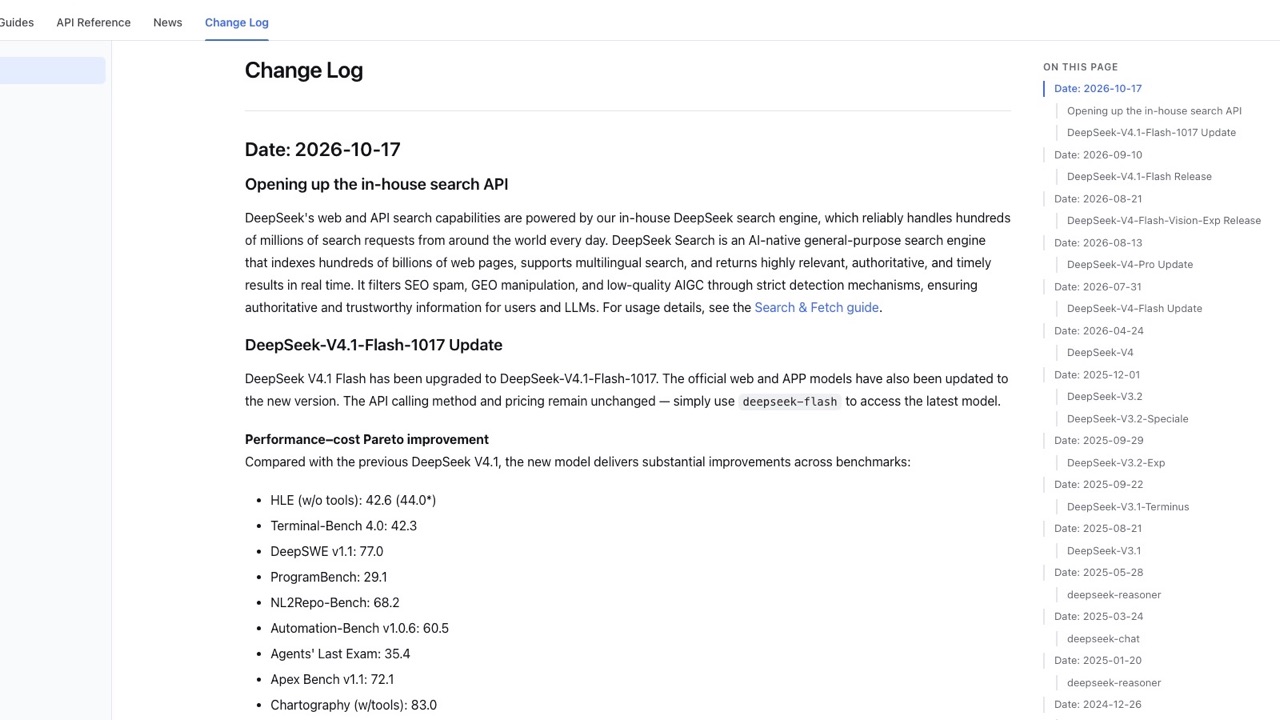
On October 17, 2026, DeepSeek upgraded DeepSeek V4.1 Flash to DeepSeek-V4.1-Flash-1017. API users still call the model as deepseek-flash. The release did not introduce another token-price cut; its practical gains are stronger coding, agent, and vision benchmarks, alongside shorter reported task runtimes and outputs. DeepSeek also opened standalone Search and Fetch APIs for real-time web discovery and Markdown extraction.
One distinction matters: “search built into the API” does not mean every model request automatically browses the web. Search and Fetch are separate JSON endpoints. They can be invoked by agent tooling, but a regular Chat Completions request does not gain live web access by itself.
What changed in DeepSeek V4.1 Flash 1017?
DeepSeek calls 1017 an incremental V4.1 Flash update, yet all 11 published benchmarks improved over the previous build. The largest gains center on terminal work, repository-level coding, automation agents, and tool-assisted vision tasks.
| Official benchmark | V4.1 Flash 1017 | Previous V4.1 Flash | Change |
|---|---|---|---|
| Terminal-Bench 4.0 | 42.3 | 31.2 | +11.1 |
| DeepSWE v1.1 | 77.0 | 74.2 | +2.8 |
| ProgramBench | 29.1 | 20.3 | +8.8 |
| NL2Repo-Bench | 68.2 | 65.4 | +2.8 |
| Automation-Bench v1.0.6 | 60.5 | 54.8 | +5.7 |
| Agents’ Last Exam | 35.4 | 31.8 | +3.6 |
| Apex Bench v1.1 | 72.1 | 64.6 | +7.5 |
These are DeepSeek’s official model-card results, not independent Roko API tests. Harness choice matters: Terminal-Bench 4.0 used the Claude Code harness, while DeepSWE v1.1 used Mini-SWE-V2. The figures support a like-for-like comparison between official releases, but they do not guarantee the same success rate on your workload.
The accurate interpretation of “faster and cheaper” is also narrower than the headline suggests: token prices did not change again on October 17. Instead, DeepSeek reports shorter task duration and output length, which can reduce the tokens and runtime required to finish comparable work. Savings will vary with prompts, tools, reasoning mode, and retry rate.
Search and Fetch APIs: separate endpoints and billing
POST /v1/tools/searchreturns structured web results and supports filters for site, language, and publication date.POST /v1/tools/fetchretrieves a selected page as Markdown.
Search is useful for source discovery; Fetch reads the chosen source in full. Each endpoint is limited to 5 QPS per account, separately from model concurrency. DeepSeek bills only successful HTTP 200 requests that return results. Failures, empty search responses, and timeouts are not charged.
Latest official DeepSeek V4.1 Flash pricing
As of October 17, 2026, deepseek-flash uses peak and off-peak pricing. Peak hours are 09:00–12:00 and 14:00–18:00 Beijing time, Monday through Friday, excluding Chinese public holidays. All other hours use the off-peak rate.
| Billing item | Off-peak | Peak |
|---|---|---|
| Cached input / 1M tokens | ¥0.02 | ¥0.04 |
| Uncached input / 1M tokens | ¥1.00 | ¥2.00 |
| Output / 1M tokens | ¥4.00 | ¥8.00 |
| Search / 1,000 successful requests | ¥5.00 | ¥5.00 |
| Fetch / 1,000 successful requests | ¥5.00 | ¥5.00 |
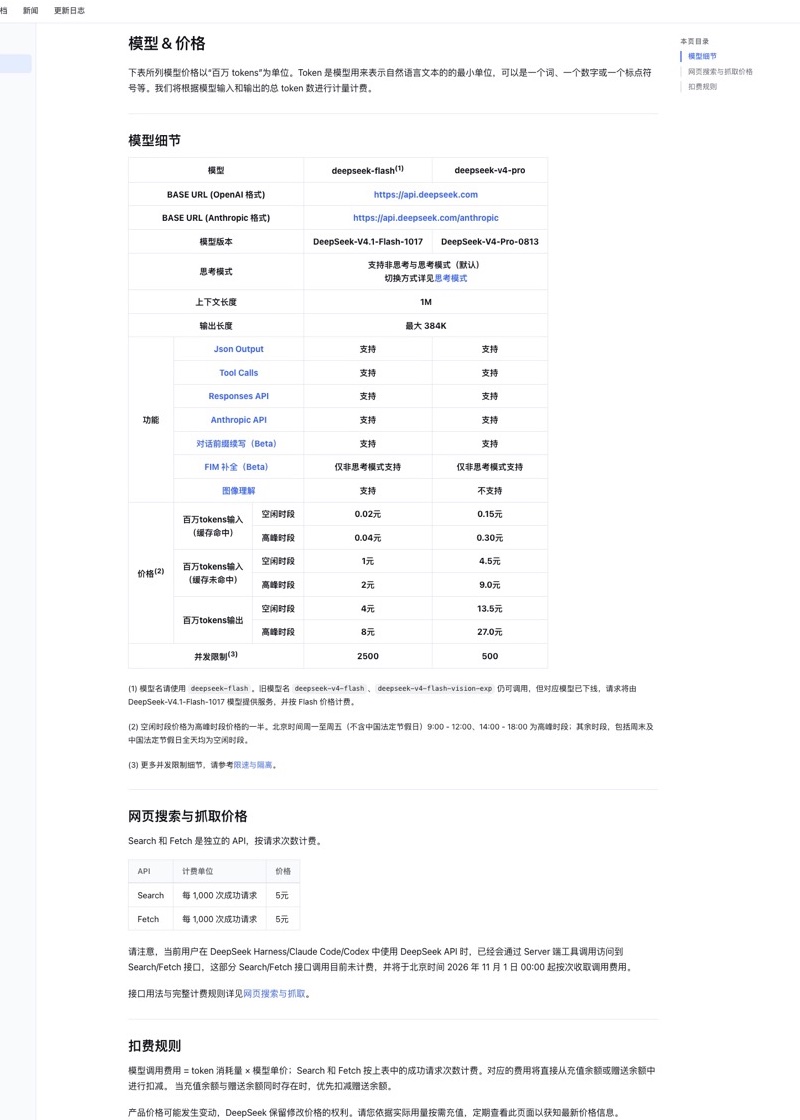
For a reproducible example, 10 million uncached input tokens plus 2 million output tokens cost about 10 × ¥1 + 2 × ¥4 = ¥18 entirely off-peak, or ¥36 entirely at peak rates. If 80% of the input hits cache, the same off-peak workload is about ¥10.16.
Search and Fetch each cost ¥5 per 1,000 successful calls, or roughly ¥0.005 per call. Server-side Search/Fetch calls made through DeepSeek Harness, Claude Code, or Codex were temporarily free at publication; the documentation states that per-call charging begins at 00:00 Beijing time on November 1, 2026.
These are DeepSeek’s direct API prices, not Roko API prices. When using Roko API, consult the live model catalog and your account billing records.
Model IDs, context window, and open weights
- Official DeepSeek API: use
deepseek-flashto receive DeepSeek-V4.1-Flash-1017. - Legacy aliases:
deepseek-v4-flashanddeepseek-v4-flash-vision-expstill resolve, but requests are routed to V4.1 Flash. - Open-weight repository:
deepseek-ai/DeepSeek-V4.1-Flash-1017. - Roko API: the public model page currently uses
deepseek-v4-flash; check the live catalog for capabilities and prices.
The official model card lists a 1M-token context window, recommends temperature=1.0 and top_p=1.0, and suggests at least 256K for max_tokens. The repository is MIT licensed and documents reasoning, tool use, and interleaved text-image input formats. Self-hosting still requires a serving stack, tool runtime, and HTTP layer.
Where does the update fit best?
- Coding agents and repository-scale work: official Terminal-Bench, DeepSWE, ProgramBench, and NL2Repo-Bench scores all improved.
- Agents or RAG systems that need current web sources: Search discovers sources, Fetch retrieves Markdown, and search calls remain separable from model-token costs.
- High-volume, cost-sensitive automation: off-peak token rates are half the peak rates, while cached input is substantially cheaper than uncached input.
- Long-context and multimodal understanding: the official specification offers 1M context and image understanding, though each gateway may expose a different subset of capabilities.
Using DeepSeek V4.1 Flash through Roko API
Visit the DeepSeek V4 Flash model page for the current Roko API model ID, price, and availability. The OpenAI-compatible API guide covers request integration.
Search and Fetch are standalone DeepSeek tools; their inclusion here does not imply that Roko API currently exposes identical endpoints. If web access is required, verify model inference and web retrieval as two separate capabilities.
Bottom line
DeepSeek V4.1 Flash 1017 is more than a benchmark refresh: it combines higher agent-oriented scores with shorter reported outputs and a first-party web-search stack. The three details to retain are that the official API model ID remains deepseek-flash, Search and Fetch are independent APIs, and October 17 did not bring another token-price change. Any cost reduction should be validated against your own completion rate, total tokens, tool calls, and end-to-end latency before migration.
Sources and verification
- DeepSeek API changelog: DeepSeek-V4.1-Flash-1017 Update — Reviewed October 17, 2026
- DeepSeek API models and pricing — Reviewed October 17, 2026
- DeepSeek Search & Fetch guide — Reviewed October 17, 2026
- Official DeepSeek Hugging Face model card — Reviewed October 17, 2026
- Cyber Zen: DeepSeek V4.1 Flash release coverage — Reviewed October 17, 2026
- QbitAI: DeepSeek model release coverage — Reviewed October 17, 2026